The concept
Hallucination: when an AI model produces something that sounds right but is false or made up. A fake policy section, a wrong number, a citation to a document that doesn't exist.
Why it happens: an LLM is not looking facts up. It predicts plausible next words (Day 15), based on patterns from pretraining (Day 18). "Section 4.7" looks like what a policy answer usually contains, so the model writes it. Fluency is not proof.
It gets worse when:
- The answer isn't in what the model saw (your company's policy almost certainly isn't).
- The question assumes something false ("What does Section 4.7 say?").
- The prompt demands an answer no matter what.
Walkthrough: the parental-leave question
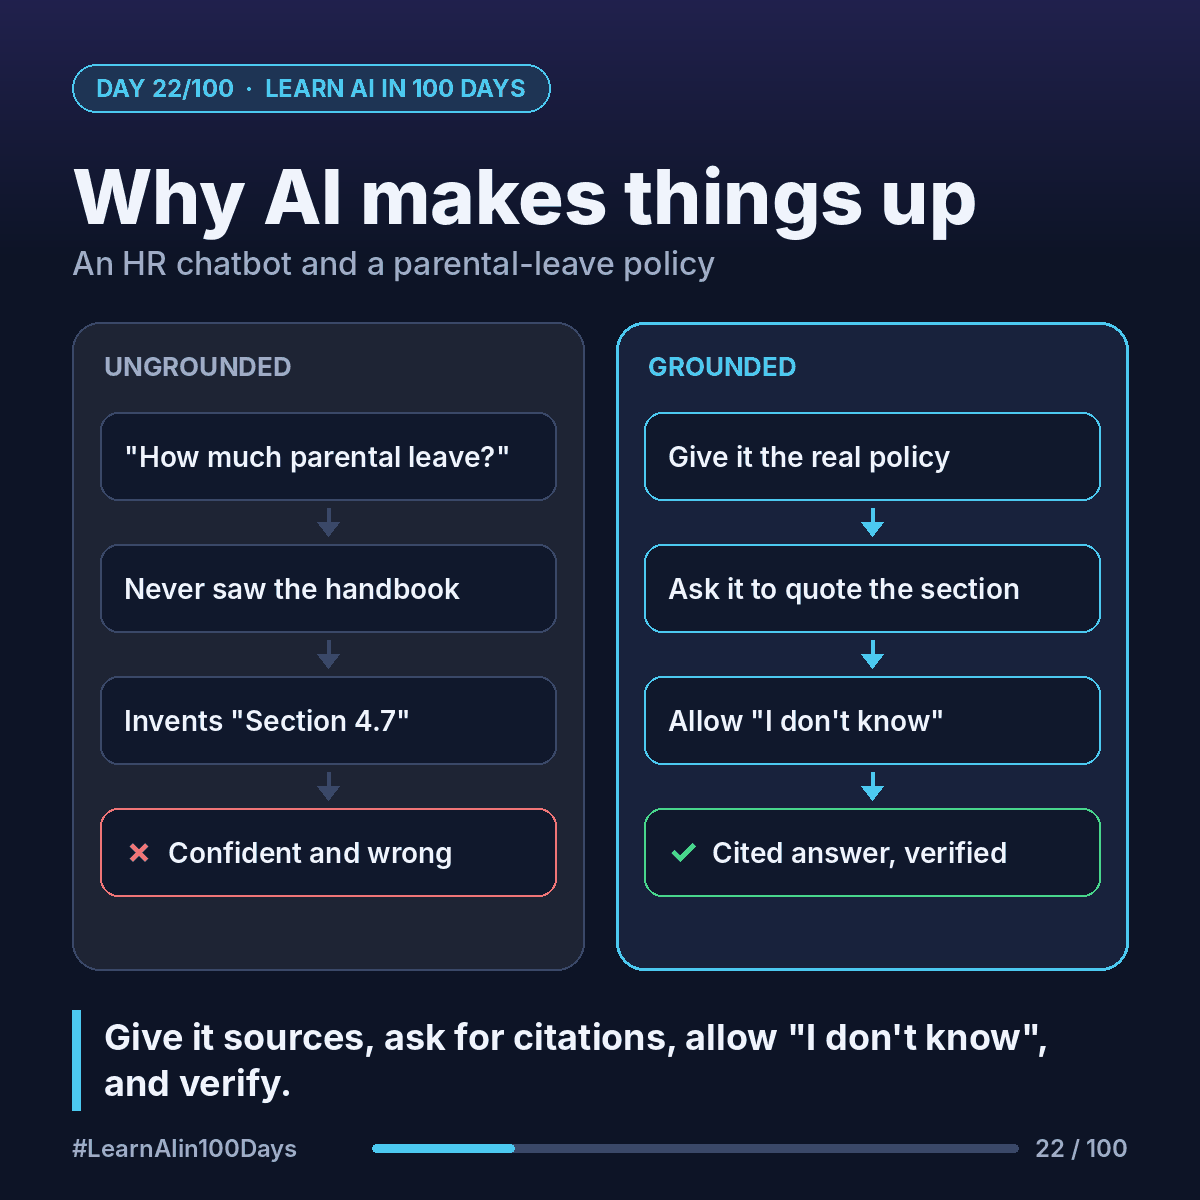
Version 1: a plain chatbot.
- Employee: "How much paid parental leave do I get?"
- The model has never seen this company's handbook.
- It blends what many handbooks say, invents "Section 4.7" and "16 weeks", and sounds certain.
- The employee plans around it. HR finds out weeks later.
Version 2: the same model, set up properly.
- Give it the source: paste or retrieve the actual leave policy into the prompt (Day 20).
- Ask it to cite: "Quote the section you used."
- Allow an exit: "If the policy doesn't say, reply 'I don't know, please contact HR.'"
- Verify: check the quote against the real document before anyone acts on it.
Result, for example: "Section 6.2 says 12 weeks paid for primary caregivers [quote]." Or an honest "I don't know." Both beat a confident guess.
Lower temperature (Day 21) can make answers more consistent, but it does not stop hallucinations. Grounding in real sources does most of the work. More on that with RAG (Day 31).
Where you see it at work
- Healthcare: a drafted patient summary that adds a medication never prescribed. A clinician must review it.
- Insurance: a claims assistant quoting a coverage limit the policy doesn't have.
- Banking: an invented fee or rate in a customer reply. That's a compliance problem, not a typo.
- Business analysis: AI-drafted requirements citing the wrong regulation clause. Check every reference.
- Product management: add "says I don't know when it should" as an acceptance criterion for any AI feature.
In one sentence
LLMs predict plausible text rather than look things up, so give them the source, ask them to cite it, let them say "I don't know", and verify anything that matters.